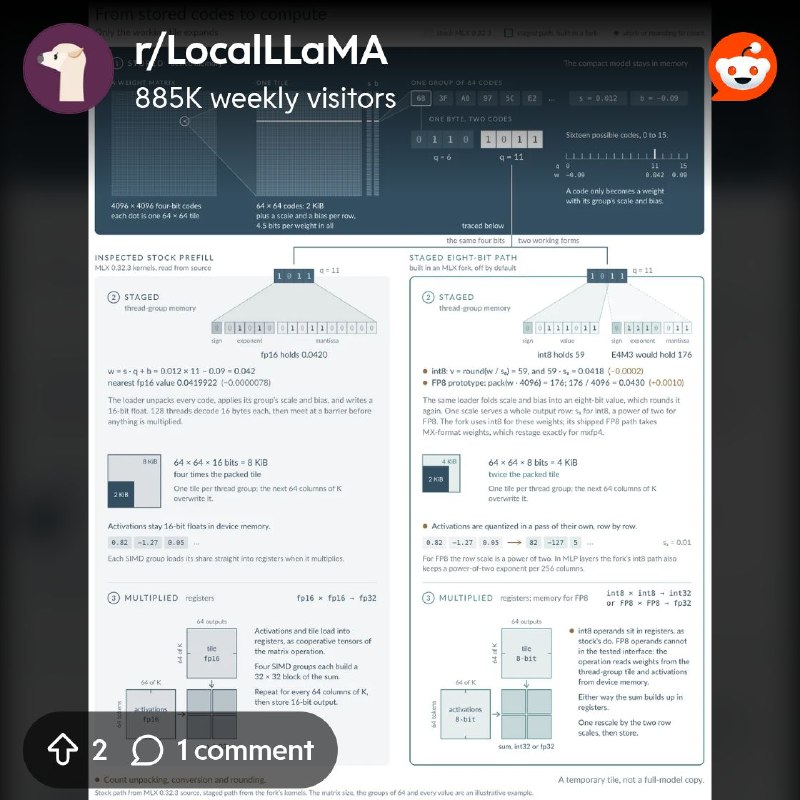

Staging quantized weights to FP8 instead of fp16: 2× M6 matrix path, +40% MLX prefill (+ int8 on M5)
Staging quantized weights to FP8 instead of fp16: 2× M6 matrix path, +40% MLX prefill (+ int8 on M5)
🌐 链接: https://www.reddit.com/r/LocalLLaMA/comments/1x13fo2/staging_quantized_weights_to_fp8_instead_of_fp16/
🏷️ 分组: Reddit|AI·自托管·VPS
🕒 时间: 2026-10-09 05:31:17
🌐 链接: https://www.reddit.com/r/LocalLLaMA/comments/1x13fo2/staging_quantized_weights_to_fp8_instead_of_fp16/
🏷️ 分组: Reddit|AI·自托管·VPS
🕒 时间: 2026-10-09 05:31:17